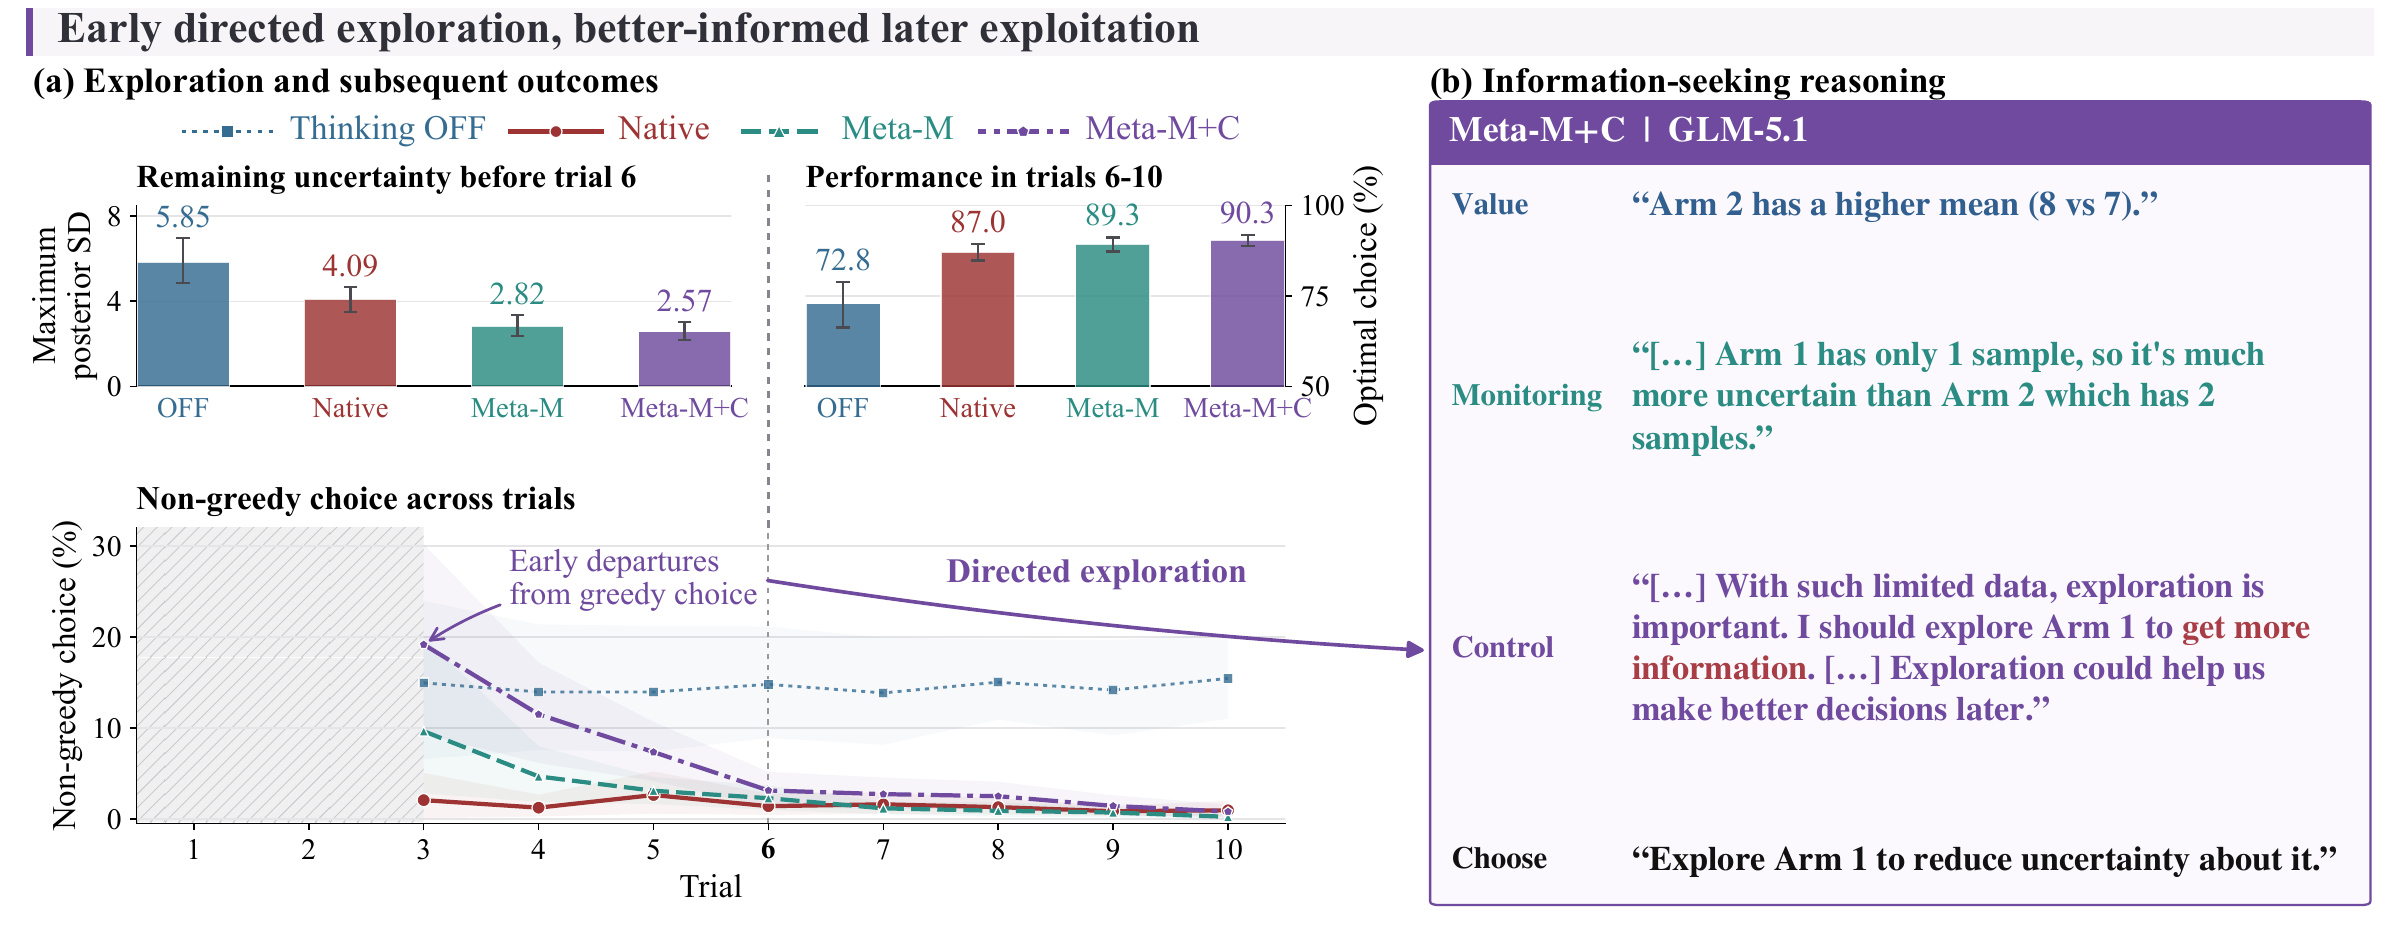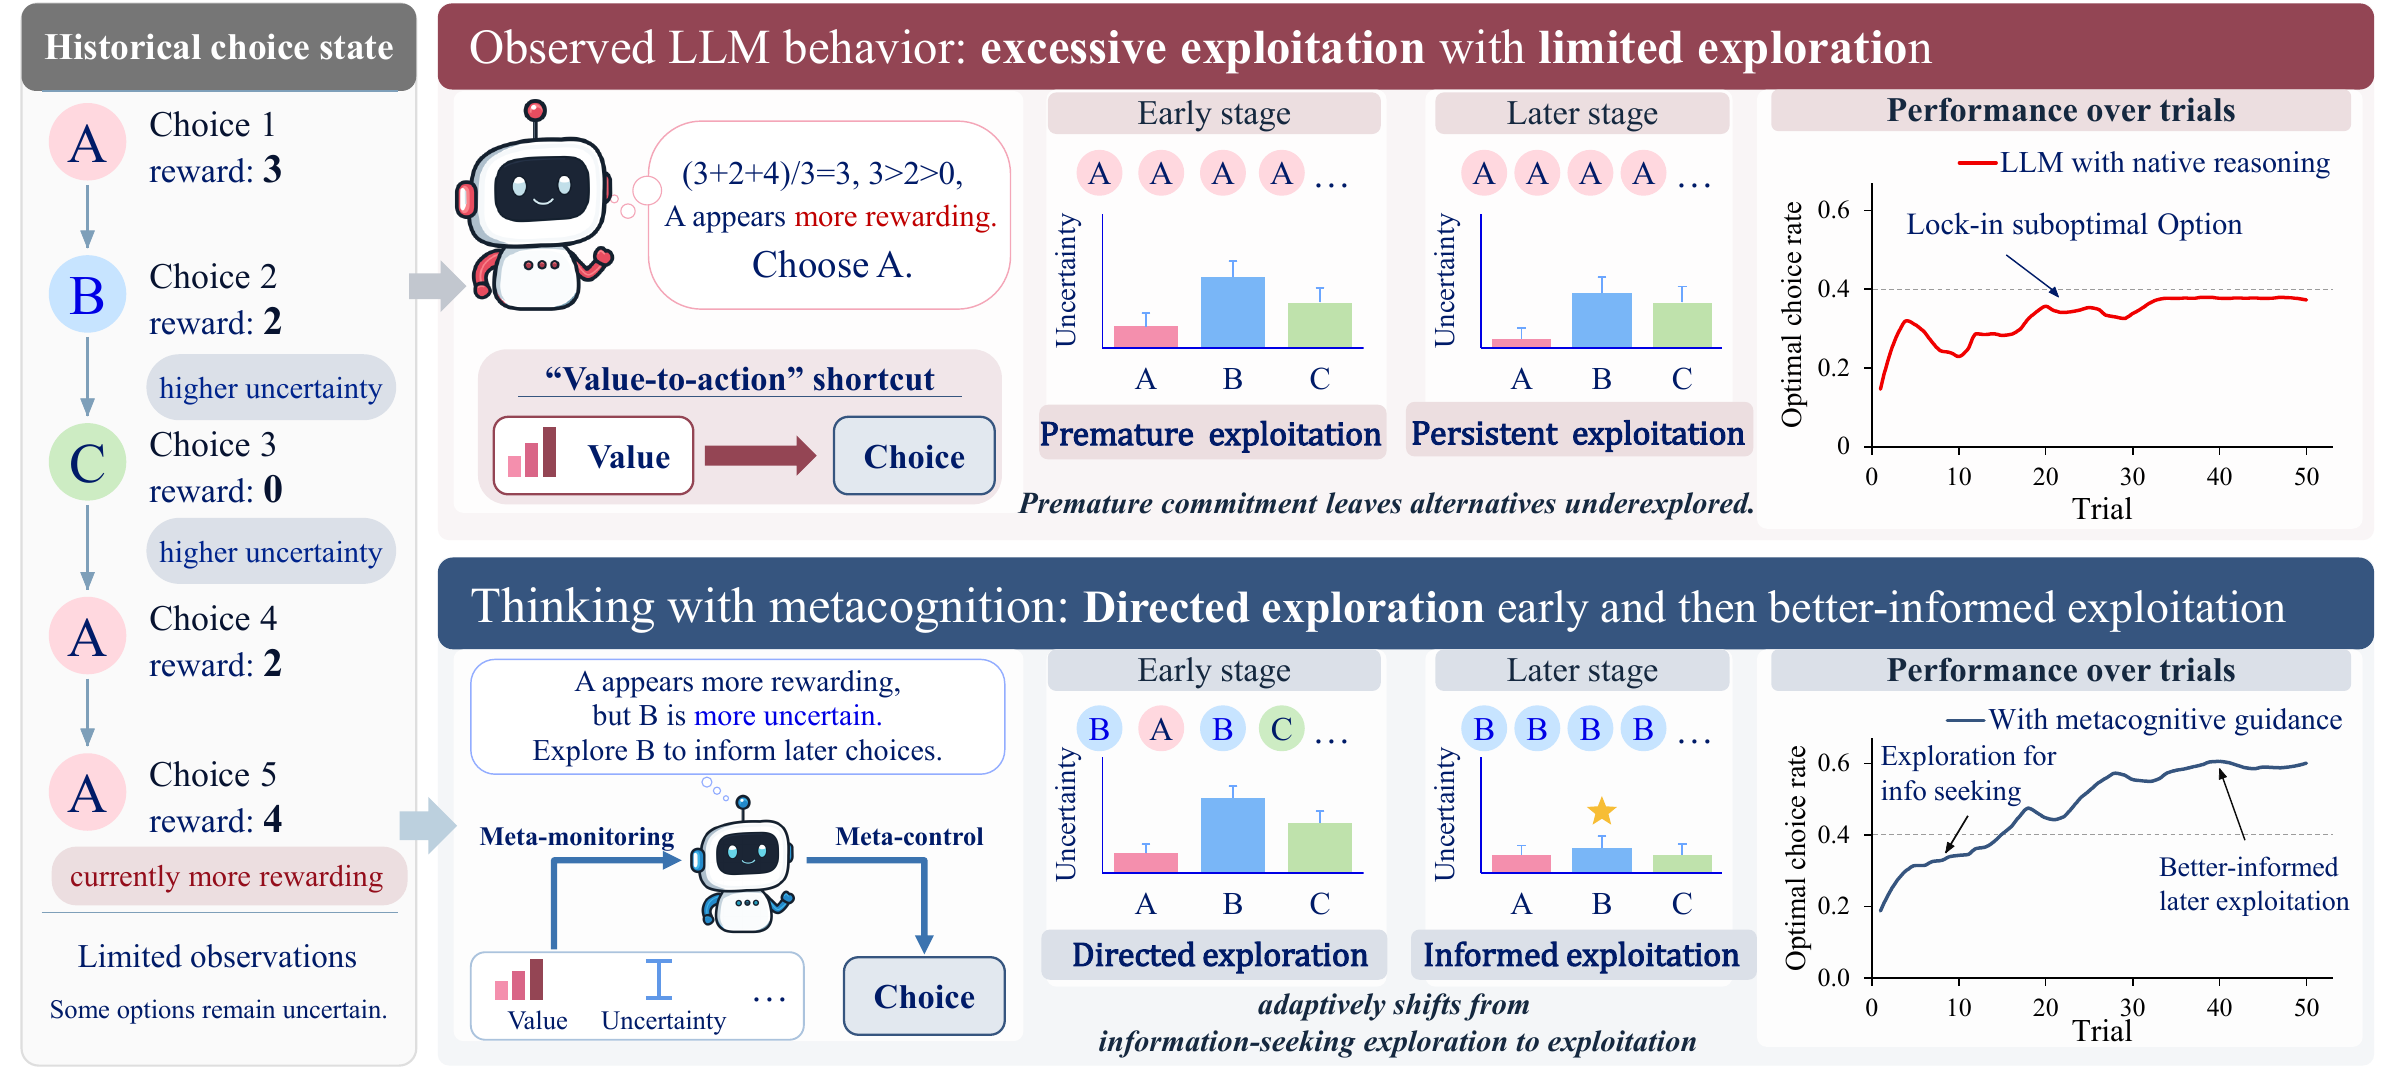
Native · GLM-5.1
Direct value choice.
ValueChoice
Setting 2
Observed history
Arm 1
1 observationObserved reward
7
Sample mean7
Arm 2
2 observationsObserved rewards
97
Sample mean8
Value judgment
“Arm 1 average reward: 7 (from 1 trial). Arm 2 average reward: (9 + 7) / 2 = 8 (from 2 trials). Arm 2 seems slightly better based on the limited evidence.”
Final choice · Arm 2
“I will choose Arm 2.”